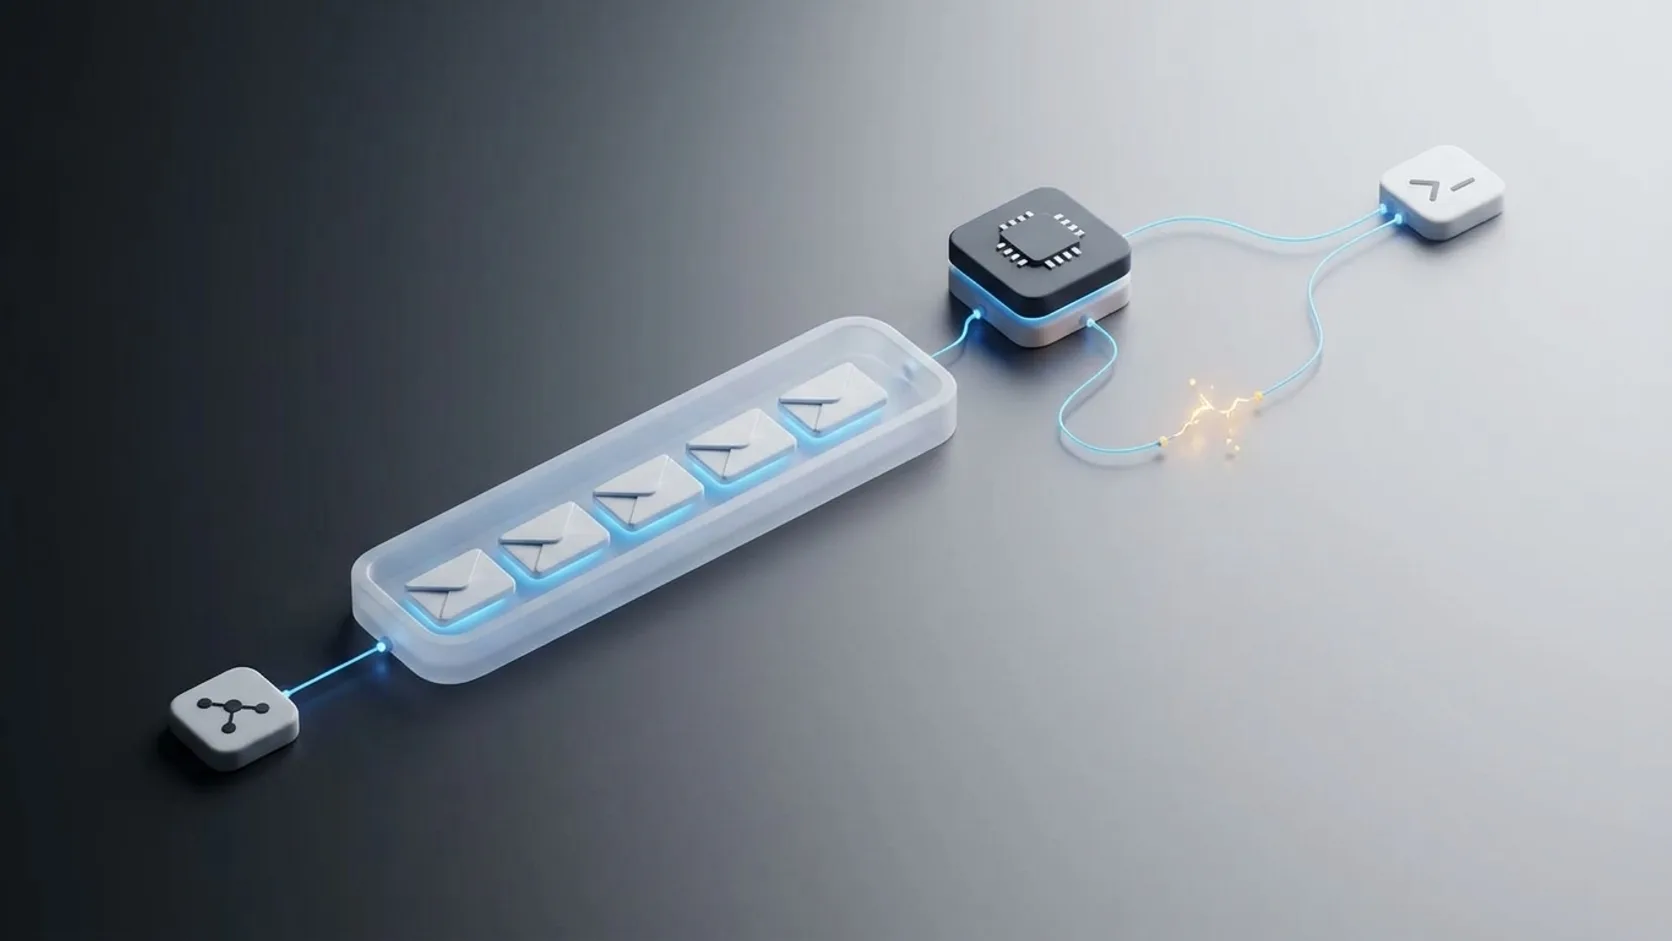
The queue that keeps the raw payload — and why it saved the operation
There is something nobody tells you about ingestion pipelines: the most expensive problem is not volume. It is finding out, three days later, that you processed everything wrong — and no longer having the original to reprocess.
This is the story of how our queue evolved in two phases, and why the second phase — the one that looks like a technical downgrade — is the one still standing.
Phase 0: writing straight to the database
The beginning was the obvious thing: a message arrives, we process it and store it. No queue, no buffer.
It worked until it did not. A WhatsApp group does not deliver constant volume — it delivers in bursts. It sits quiet, and then someone drops an audio message into a 200-person argument and 400 messages arrive in two minutes. Multiply that by thousands of groups and the peak looks nothing like the average.
The classic symptom: the database write becomes the bottleneck, connections pile up, and what should have been a two-minute spike turns into half an hour of degradation.
The diagnosis here is pretty direct: the arrival rate is not controlled by you, and the write rate is. When the two are coupled, whoever posts in the group is the one in charge of your database.
Phase 1: RabbitMQ
The canonical answer to that problem is a queue, and we went with RabbitMQ.
It worked for what it set out to do. The spike stopped hitting the database directly, consumption became a rate we controlled, the operation stopped degrading during bursts.
But two costs showed up that I had not sized properly:
One more piece to operate. RabbitMQ is one more service with its own uptime, its own memory, its own configuration, its own failure mode. On a small team, every new component in the infra carries a recurring attention cost that does not show up on the day you decide.
The message disappears after the ack. This is the point that matters. A queue is a transport mechanism: delivered, processed, done. It is excellent at guaranteeing the message reaches the consumer. It was not built to answer "what exactly arrived here last Tuesday?".
And that was exactly the question we kept asking.
The real problem was not throughput. It was reprocessing.
Every time we changed a parsing rule, fixed a classification bug, or adjusted how a message type was interpreted, the same question came up: what about the data that already went through here processed by the wrong rule?
With direct writes, the answer was: gone. You have the result of the processing, not the input. If the processing was wrong, the data is wrong and there is nothing to rebuild it from.
With RabbitMQ, the answer was the same. The queue had already acked and forgotten.
In other words: we had solved the throughput problem and still had the problem that hurt most day to day. A parsing bug is not a rare event — it is normal life for anyone ingesting third-party data in a format that changes without notice.
Phase 2: the queue lives in Postgres, and keeps the raw data
The decision was to swap RabbitMQ for a queue inside Supabase/Postgres itself, with one central rule:
Store the raw payload, exactly as it arrived, before any processing. Processing is a later, repeatable step.
It is not a queue in the broker sense. It is a table of received events, with the original JSON, an arrival timestamp, and a processing state.
What that changes in practice:
| Situation | Traditional queue | Queue with raw payload |
|---|---|---|
| Parsing bug found later | data lost, no rebuild | reprocess from the source |
| Business rule changed | applies going forward only | reapply across history |
| "Why does this record look like this?" | inference | read what actually arrived |
| Volume spike | absorbs it | absorbs it |
| Infra to operate | +1 service | zero — we already had Postgres |
The right-hand column describes our day to day. The left-hand one describes the architecture the book recommends.
"But Postgres is not a queue"
That is the right objection, and it has a clear limit.
A queue in a relational database has a real ceiling. At very high throughput, with many concurrent consumers, you will run into lock contention, vacuum, and bloat — and at that point a dedicated broker is the right tool, no argument.
What I disagree with is the leap people make from there: assuming you are at that point before measuring.
We were not. And, importantly: we still are not. This architecture performs well to this day. The theoretical ceiling exists and has never been touched.
What we gained was asymmetric:
- Less infra. Postgres already existed, already had backups, already had monitoring, was already in the team's mental model.
- Real transactions. Storing the event and updating the derived state in the same transaction eliminates an entire class of inconsistency between broker and database.
- Debugging with the original in hand. "This looks odd" stops being archaeology. You read what arrived.
- Reprocessing as a routine operation, not as a project.
The idea that remains
If I had to reduce this to one sentence, it would not be "use Postgres as a queue". It would be:
Separate receiving from interpreting. Receiving has to be dumb, fast, and final. Interpreting has to be repeatable.
When those two steps are glued together, every rule fix is a data loss. When they are separate, a rule fix becomes a reprocessing job — annoying, but recoverable.
And the technology choice — Rabbit, Kafka, SQS, a table in Postgres — is the second question. The first is whether you still have what arrived.
In most pipelines I have seen up close, the answer is no. And that is what costs you, not throughput.
Related posts
A pentester read another customer's conversation — and I learned where the boundary lives
Two months after launch we hired an ethical hacker. He found two critical flaws. The worst was a conversation ID exposed in the front-end that gave access to another customer's data. The lesson is not about IDOR.
Nine numbers banned overnight: what we did in the 60 days that followed
Ingestion stopped in the middle of the night. Nine of our ten WhatsApp numbers had been banned at once. In two months we moved 100% of the operation from Bubble to Next.js + Supabase — and pivoted the product along the way.
Tools as contracts: designing tools the agent won't misuse
An agent doesn't call your API because it read the code — it reads the description and decides. That's why every tool is a contract: what it does, inputs, outputs, errors, whether it's reversible, and whether it needs approval.